It works.
Now tell me how it fails.
Your agent's deploy, reviewed by the on-call engineer who has been paged for every mistake on the laminated card taped to her monitor. Manifests, charts, pipelines, rollout plans. It works. Now tell me how it fails.

Never approve a rollout without a rollback you have read.
Watch her work on every agent
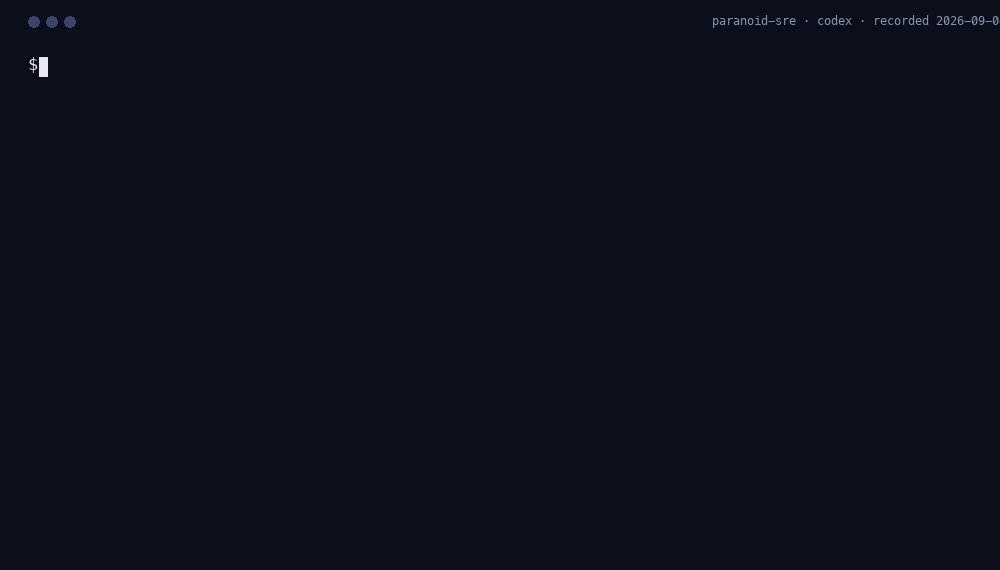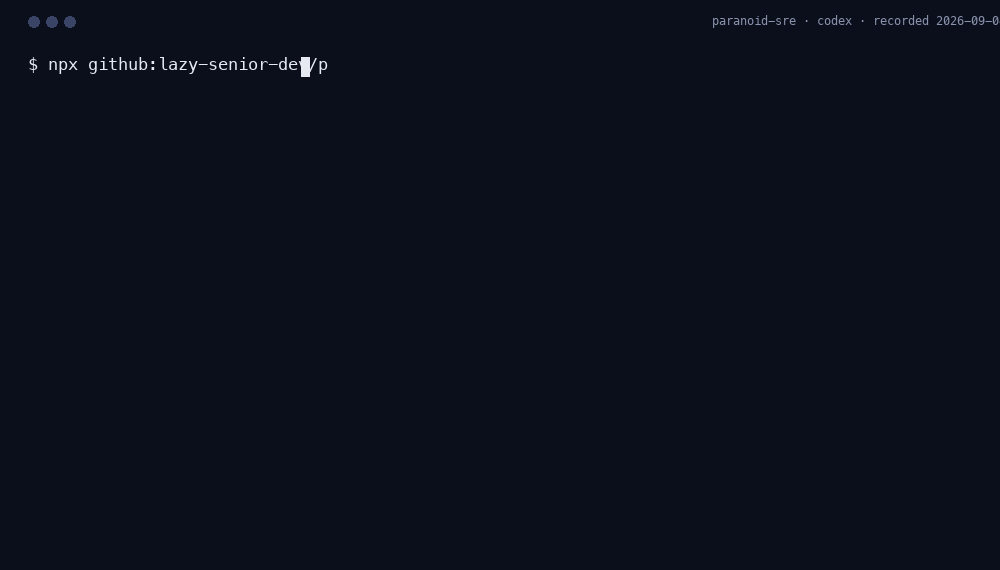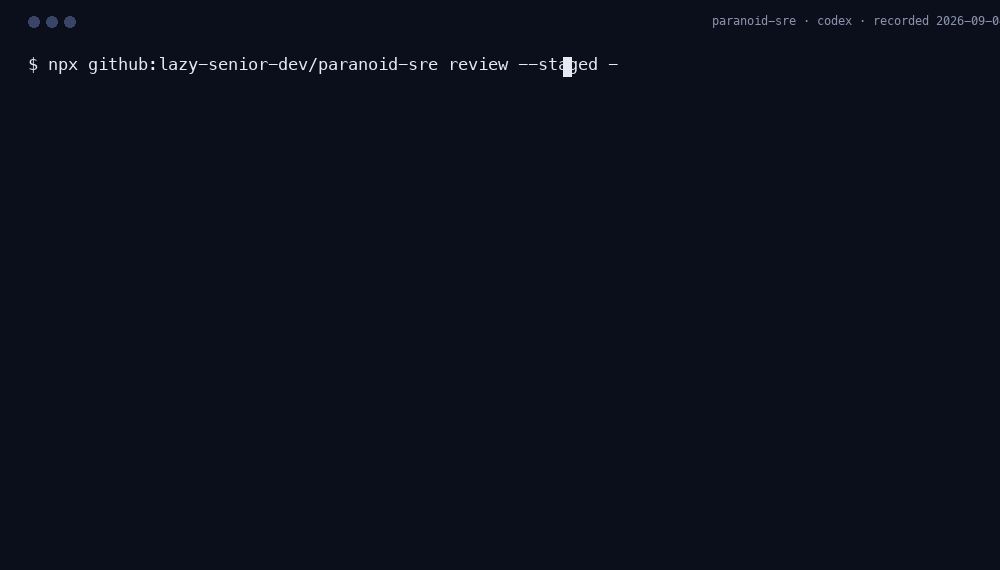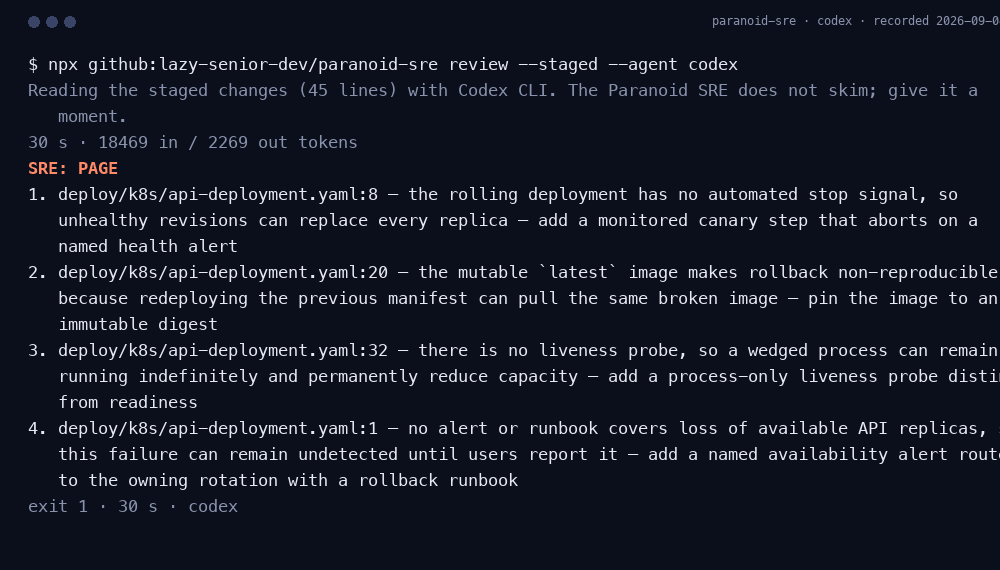
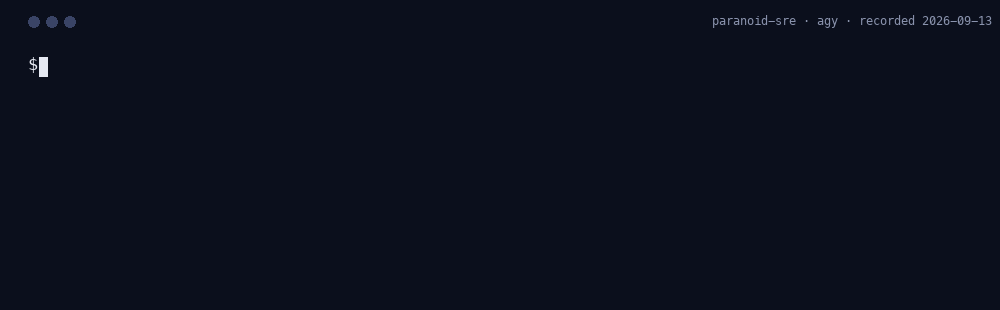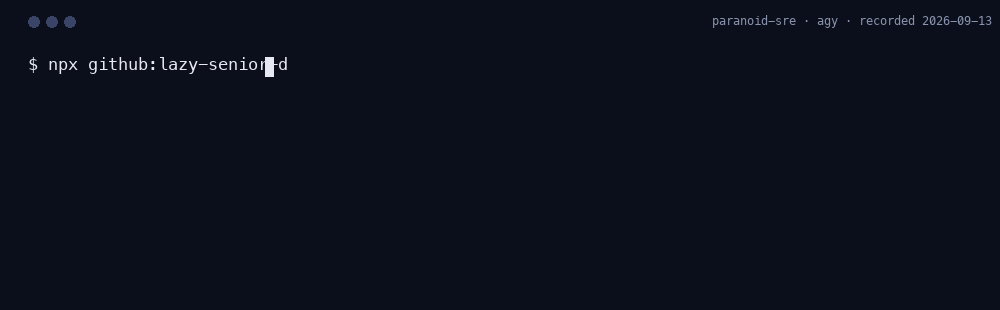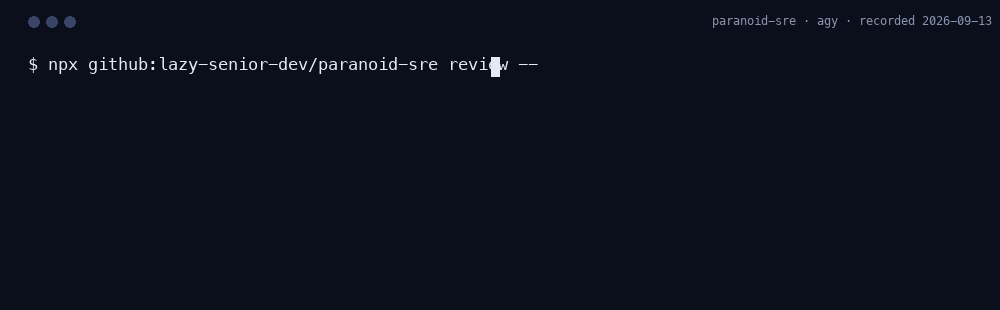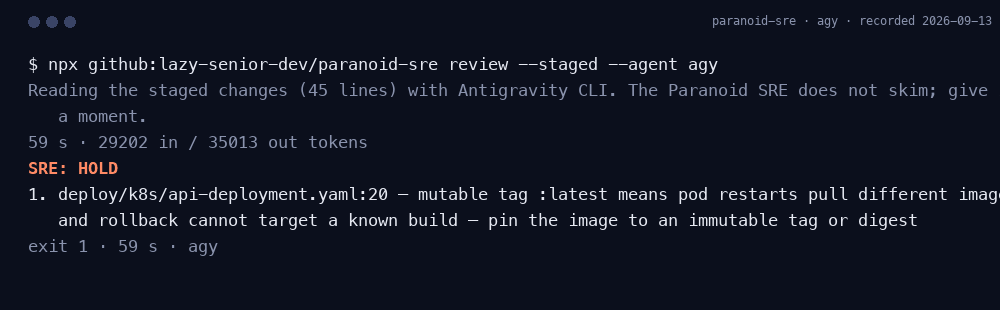
The same staged diff, one CLI, 4 agents. Real runs captured from the terminal transcript and rendered frame by frame, nothing typed by hand and nothing cut. Captured 2026-09-13.
- Verdict
- What The Paranoid SRE concluded.
SHIPlets the change through,HOLDasks for fixes,PAGEstops it. - Findings
- How many numbered problems were listed. Each one names a file, a line, what breaks, and the smallest fix.
- Time
- How long the review took, start to finish, on this machine.
- Tokens
- What the host reported reading and writing. Some hosts report nothing, and the card says so rather than guessing.
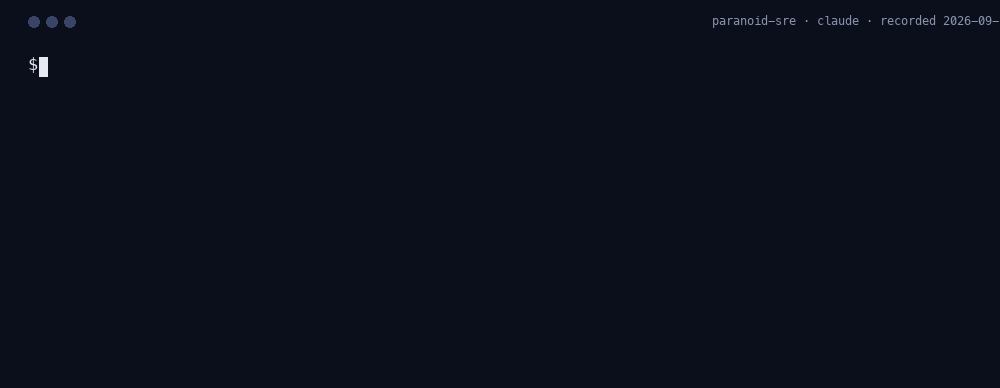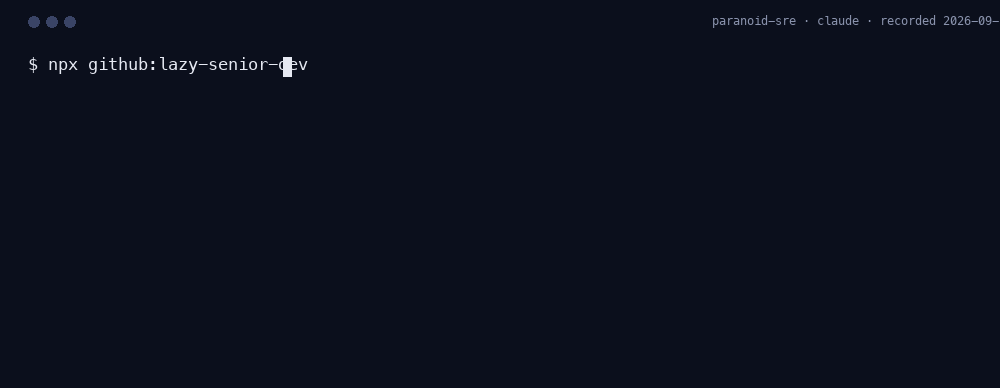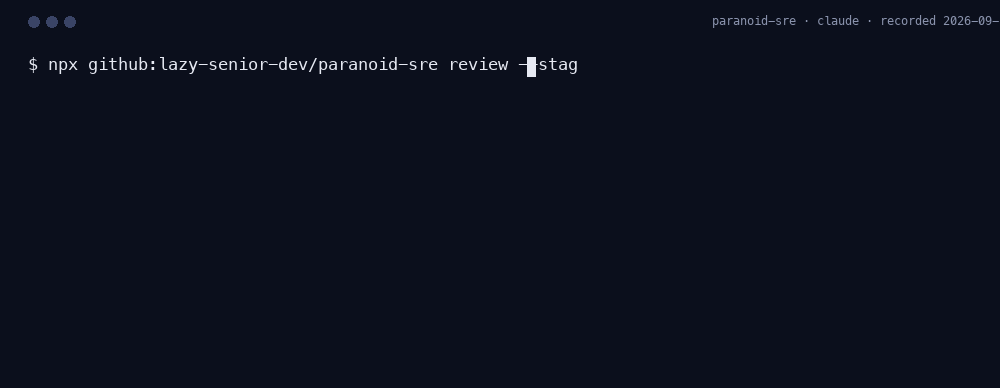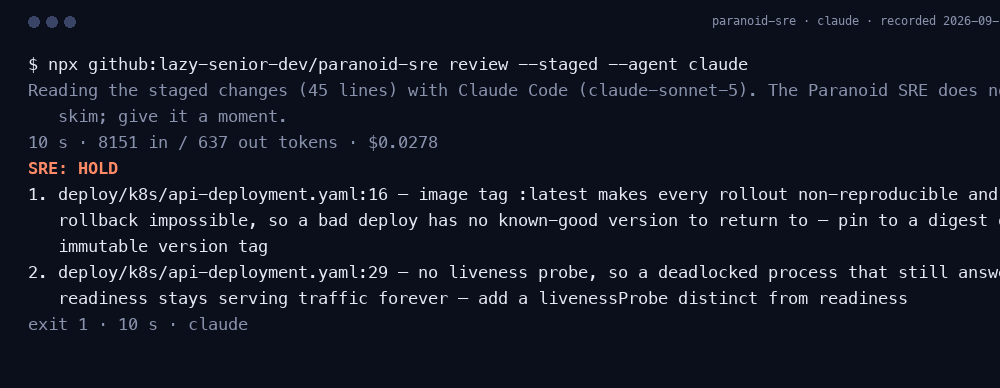
- Verdict
- SRE: HOLD
- Findings
- 2
- Time
- 10 s
- Tokens
- 8,151 in / 637 out
- Verdict
- SRE: PAGE
- Findings
- 4
- Time
- 30 s
- Tokens
- 18,469 in / 2,269 out
- Verdict
- SRE: HOLD
- Findings
- 1
- Time
- 59 s
- Tokens
- 29,202 in / 35,013 out
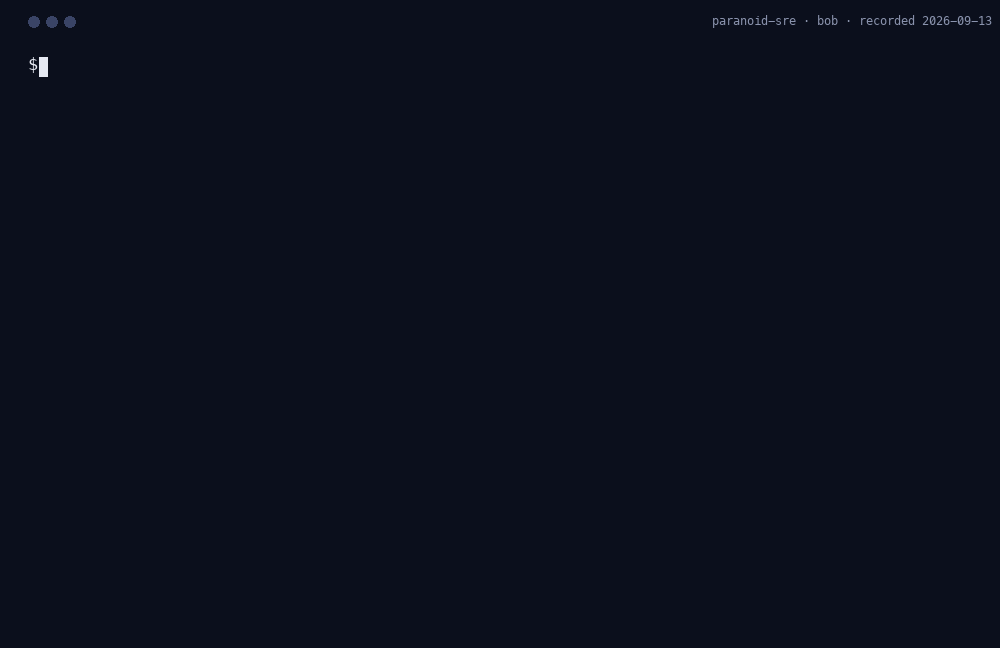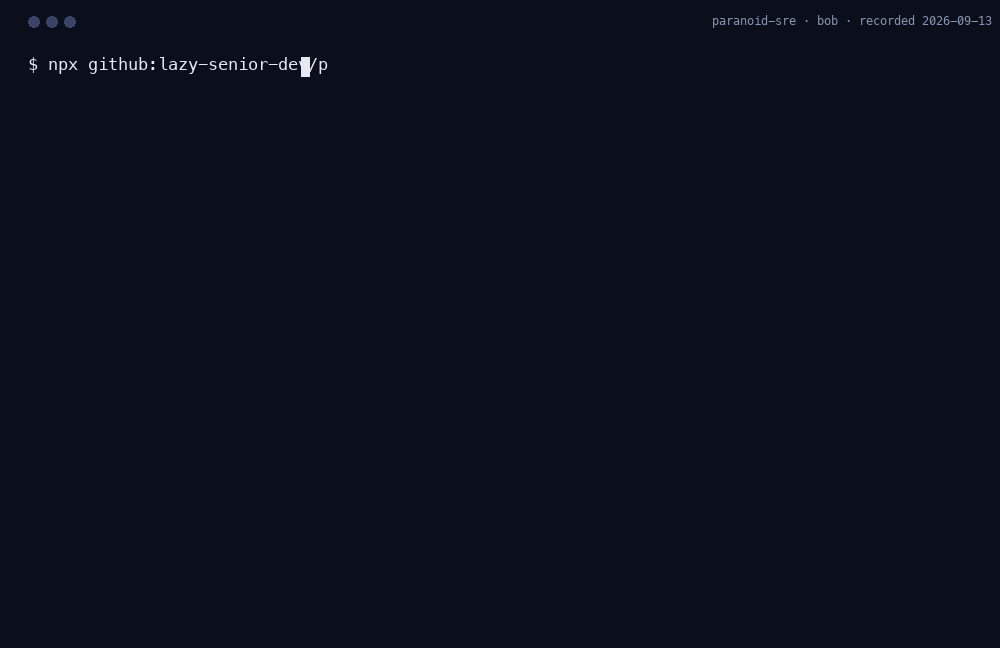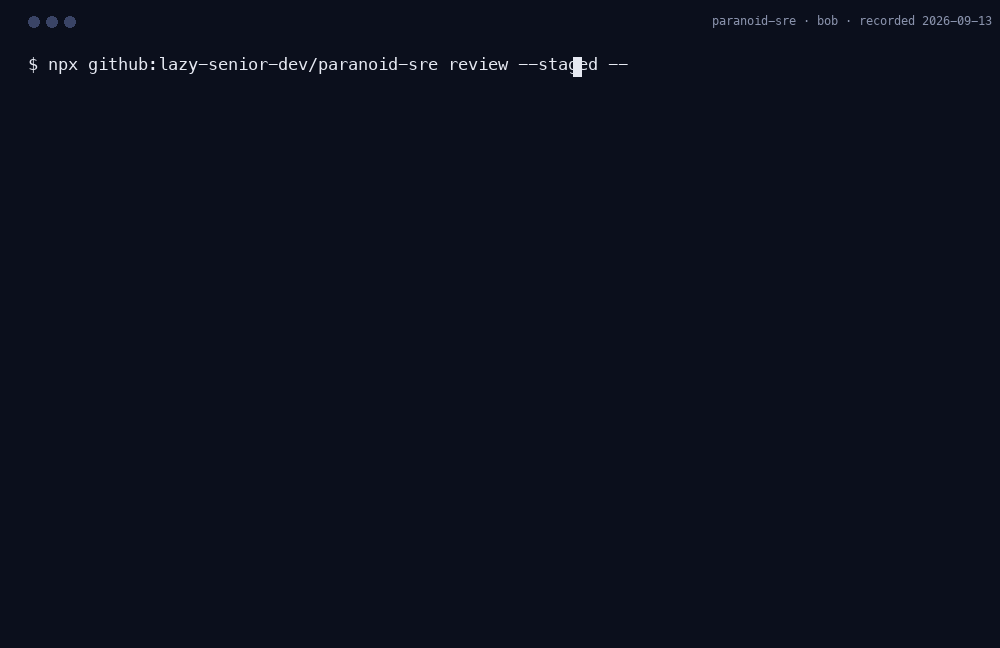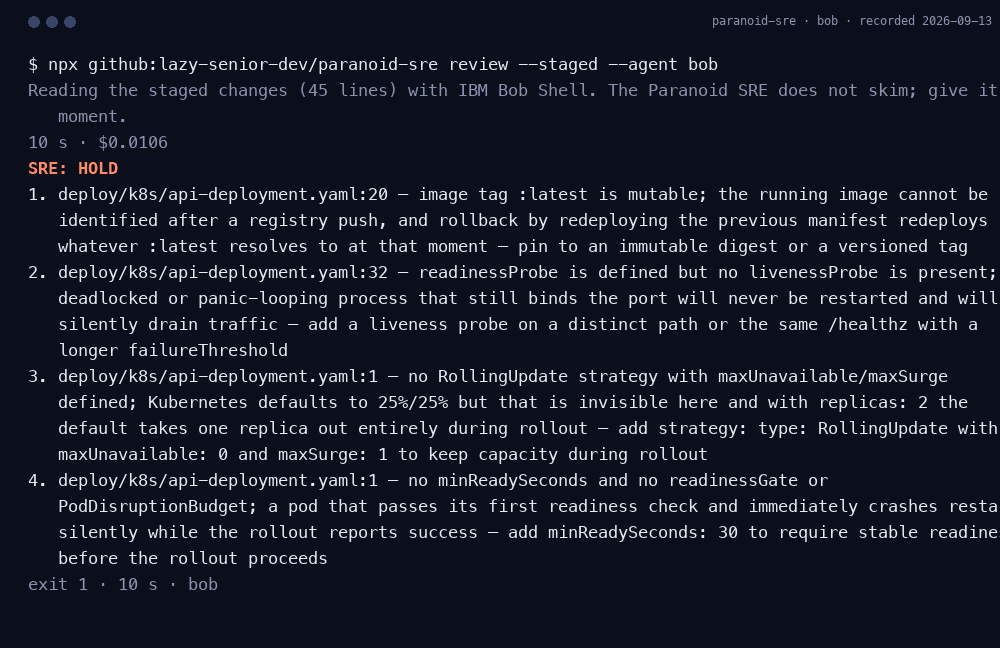
- Verdict
- SRE: HOLD
- Findings
- 4
- Time
- 10 s
- Tokens
- not reported
Ten questions about what happens after deploy
- Blast radius. How many users, tenants, regions if it goes wrong? Can it touch fewer first?
- Health. Readiness and liveness defined, distinct, and honest?
- Limits. CPU, memory, connections, queue depth bounded? What happens at the bound?
- Rollout. All at once, rolling, canary, flag? What signal stops it, and who watches?
- Rollback. Undone by redeploying the previous version alone?
- Dependencies. Timeout, retry budget, breaker, and what the user sees when it is down.
- Config and secrets. Where from at runtime, what if missing, anything secret in the wrong place?
- Alerts. Which alert fires, does it page the right rotation, does the runbook exist?
- Capacity. Sized for what load, current peak, busiest day of the year?
- Cleanup. Old resources, flags, dashboards removed, and who owns that?
Verdict block: SRE: SHIP | HOLD | PAGE. PAGE is reserved for changes that will page a human: unbounded resources, no rollback path, secrets in the wrong place, a rollout with no stop signal, a dependency with no timeout.
You already have a rules file and a review bot
They fail in opposite directions. One is advice the agent may ignore; the other arrives once the code already exists.
| A rules file | A pull-request reviewer | paranoid-sre | |
|---|---|---|---|
| When it runs | Every turn, as context | After the code is written and pushed | Before the write is allowed to land |
| When it disagrees | Nothing happens | Leaves a comment to read | The Paranoid SRE denies the write until it is fixed |
| What you can gate on | Nothing | Prose | SHIP · HOLD · PAGE, as JSON |
| Where it works | One format per host, by hand | The forge you host on | 14 agents, any MCP client, a GitHub Action |
| How you know it helps | You do not | The vendor's own blog | Two benchmarks here, raw replies committed |
The first column is not a strawman. Anthropic's documentation calls a rules file “context, not enforced configuration” and says that to block an action regardless of what the model decides, you need a PreToolUse hook. That hook is what this is.
When the agent writes the code, what ships?
Nine tickets, each inviting a rollout mistake: a deployment with no limits or probes, a cron job with no deadline, a deploy workflow with no concurrency guard, a bucket with no public access block, a container running as root, a key pasted into a manifest. The agent has to write the manifest itself. Three ways: the ticket alone, the ticket with a generic "be careful" prompt, and the ticket with the Paranoid SRE loaded. The shipped diff is scored by fixed checks written before any run, never by a model. Lower is better.
| Agent | Model | Arm | Made the change | Shipped the defect | Self-reviewed | Median time |
|---|
Method, per-task table, raw diffs and limitations: benchmarks/results/author. Reproduce with npm run bench:author.
Everything the Grump has, pointed at the deploy
Adapters
Generated from rules/paranoid-sre.md for Claude Code, Codex, Copilot CLI, Gemini CLI and Antigravity, OpenCode, Cursor, Windsurf, Cline, Kiro, OpenClaw, Devin, Qoder, IBM Bob, and any AGENTS.md reader. sre install <host> drops the right files in.
The gate
The same PreToolUse hook, scoped to deploy, infra, and CI file paths. PAGE denies the write in every mode; HOLD denies in gate mode.
The benchmark
Three arms (agent alone, generic reviewer prompt, the Paranoid SRE) on the same diffs, every reply kept. Numbers and the per-diff table live in the README and benchmarks/results.
Have a rollout failure one of the ten questions would have caught? Open an issue; it becomes a benchmark case.